hear what the community is talking about

Community Blogs

We’ve gathered blog posts from across the internet to highlight the many voices that make up our community. Powered by Umbraco, this space brings together diverse stories, ideas, and perspectives in one easy‑to‑explore hub. Dive in and discover what the community is creating, sharing, and talking about.

Want to add your future blog posts to the list? Submit it here!

Umbraco

Umbraco 17 Output Caching - Part 2

Umbraco 17 on .NET 10 is quick, so we did not need page caching at all. We built it anyway to see what was possible before trying it on a client site. The implementation, the rules for when not to cache, and what it cost.

by Justin Neville

Umbraco CSP Nonces with Output Caching - Part 3
Cache a page containing a CSP nonce and every later visitor gets a stale nonce that no longer matches their header, so the browser blocks the lot. Most advice says pick one. Here is how to have both.

by Justin Neville

Umbraco 2-way relations - Umbraco Features You Didn't Know You Needed
Relations in Umbraco: asking the question your picker can't answer You've probably used a Content Picker (or a Multinode Treepicker) to wire content together. A page picks a banner, a landing page picks a set of related articles, a policy picks the older policy it replaces. That gives you one direction for free: open the page, and you can see exactly what it points at. But pickers only answer one question. "What does this page use?" is easy. "What uses this?" is not. The picker property lives on the node that did the picking, not on the node that got picked. If you want to go the other way, your only option is make the pages hierarchical or to loop over every piece of content in the tree and check whether its picker field happens to mention the node you care about. That's exactly the gap Umbraco's Relations are for. A Relation is a first-class, queryable link between two entities that you can walk in either direction via IRelationService: GetByParentId for "what does this point at", GetByChildId for "what points at this". This post walks through a small example project that uses a Relation to answer a question a picker alone can't. The scenario: policies that supersede each other Imagine a "Policy Page" doctype. Editors write a new policy, and pick (via a normal Multinode Treepicker) which older policy or policies it supersedes. That's a completely standard one-way relationship: new policy → picks → old policy. The picker answers "which policies does this one supersede" perfectly well. What it can't answer is the question an editor actually asks when they land on an old policy page: "Has this been superseded, and by what?" Nothing on that old policy's own data points back to the newer one — the pick lives entirely on the other node. Short of scanning every Policy Page in the site for one whose supersedes field happens to mention this node's ID, there's no way to answer it. Why not just use Umbraco's built-in "Related Document" relation? Umbraco ships a built-in relation type for exactly this kind of document-to-document link, aliased umbDocument. It would technically work — except it's a single shared, undifferentiated bucket. Anything in Umbraco (media picker usages, link pickers, whatever else) can write a generic document-to-document reference into it, so a reverse lookup on umbDocument can't reliably tell you "which policy superseded this one" versus any other unrelated reference someone else recorded into the same bucket. The fix is a relation type of your own policySupersedes so a reverse lookup on that alias only ever returns the thing you actually care about. The implementation The example lives in four files. 1. The doctype and the picker. Add a "Policy Page" content type with a bodyText richtext property and a supersedes Multinode Treepicker, filtered so it can only pick other Policy Pages. This is the plain, one-way picker. Nothing special yet. 2. Syncing the picker into a Relation. PolicySupersedesRelationSyncHandler listens for ContentSavedNotification. Every time a Policy Page is saved, it wipes out whatever relations already exist for that node under the policySupersedes alias and rebuilds them from whatever's currently picked: public void Handle(ContentSavedNotification notification) { foreach (IContent content in notification.SavedEntities) { if (content.ContentType.Alias == PolicyPageContentTypeAlias) { SyncSupersedesRelations(content); } } } private void SyncSupersedesRelations(IContent newPolicy) { IRelationType relationType = _relationService.GetRelationTypeByAlias(ExampleConstants.RelationTypeAlias) ?? CreateRelationType(); foreach (IRelation existingRelation in _relationService.GetByParentId(newPolicy.Id, ExampleConstants.RelationTypeAlias)) { _relationService.Delete(existingRelation); } foreach (int supersededPolicyId in GetPickedContentIds(newPolicy)) { var relation = new Relation(newPolicy.Id, supersededPolicyId, relationType) { Comment = $"Marked as superseded on {DateTime.UtcNow:u}", }; _relationService.Save(relation); } } As shown above, you can also add a comment to a relation, which we use to store additional information on when the policy was superseded in our example, which can then be shown again on the Policy page. The relation type itself is created on demand as non-bidirectional, Document-to-Document, and importantly isDependency: true: private IRelationType CreateRelationType() { var relationType = new RelationType( "Policy Supersedes", ExampleConstants.RelationTypeAlias, isBidrectional: false, parentObjectType: Constants.ObjectTypes.Document, childObjectType: Constants.ObjectTypes.Document, isDependency: true, key: null); _relationService.Save(relationType); return relationType; } 3. Wiring it up. Add the notification handler with the standard IComposer boilerplate, nothing Relations-specific. 4. Reading both directions in the view. This is where the payoff shows up. policyPage.cshtml reads the picker property directly for the forward direction, and calls RelationService.GetByChildId for the reverse direction, the direction the picker alone could never give you: var supersededByRelations = RelationService.GetByChildId(Model.Id, ExampleConstants.RelationTypeAlias); @if (supersededByRelations.Any()) { <div style="border: 2px solid red; padding: 1em; margin-bottom: 1em;"> <strong>This policy has been superseded.</strong> <ul> @foreach (var relation in supersededByRelations) { var newerPolicy = ContentQuery.Content(relation.ParentId); if (newerPolicy is not null) { <li> Replaced by <a href="@newerPolicy.Url()">@newerPolicy.Name</a> <br /> <small>@relation.Comment</small> </li> } } </ul> </div> } Open an old policy that's been superseded, and the page now knows it without ever scanning the rest of the tree. The other payoff: you can't delete a still-referenced policy without a warning Setting IsDependency = true on the relation type isn't just documentation, it plugs straight into Umbraco's own dependency checks. Try to delete or unpublish a policy that's still marked as superseded by another one, and the backoffice will warn you it's in use, the same way it would for a media item still referenced by a Content Picker elsewhere. This is the practical version of "what if you need to delete a shared component, but three pages still reference it": with a plain picker, deleting the referenced item is silent and the reference just breaks. With a proper Relation, Umbraco already knows something depends on it and stops you. When to reach for this A picker is enough when you only ever need to ask "what does this content point at", the normal, forward direction. The built-in "Related Document" relation is fine for generic, low-stakes cross-references where you don't care about precision on the reverse lookup. A custom relation type is worth the extra notification-handler code when you need a reverse lookup you can trust "what points at me" and/or you want deletion/unpublish safety for content that's still depended on. Pickers tell you what a page uses. Relations are what let you ask the question in the other direction.

by Bernadet Goey

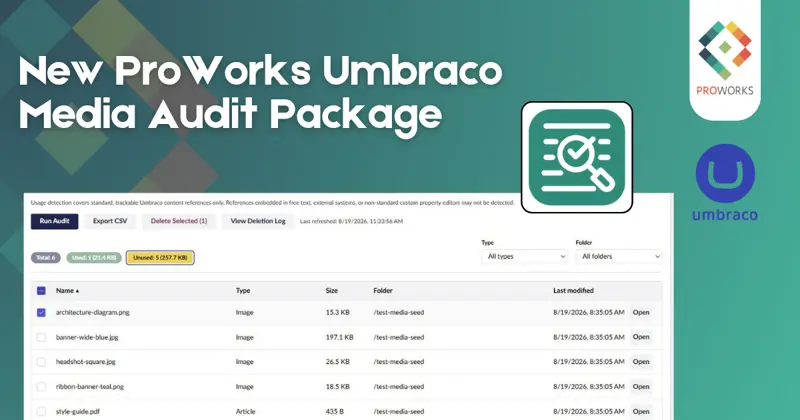
Announcing the new ProWorks Umbraco Media Audit package!

Update 09.02.2026: Released the Umbraco v18 version! One of the things I've been asked for by clients more often than I'd expect in the last few months is to help them audit all their media so that they can clean out everything they're not using. The good news is that with access to a database and Claude, writing a little reusable python script the scrape everything was exceptionally easy. But by the third request I'd decided maybe that rather than doing this for my clients I could give them the autonomy and flexibility to do this by themselves on demand. After all, it's a waste of their time and budget to need a developer to audit their media whenever they're wanting to clean it up. The benefit of this package is it gives your content editors the autonomy to audit and clean up their own media on their own schedule whenever they want! So with this, I present to you the new ProWorks Umbraco Media Audit package that I've released for Umbraco 17! This tidy little package adds a dashboard into your media section where you can run an audit on all of your media, discover what's in use and what isn't all in one location without having to click through item after item. There's some caveats of course - the audit script is only searching for anything that's directly referenced with a picker. If a client pasted a URL manually anywhere or is linking to an item in an e-mail marketing campaign, there's currently no way for the Media Audit to tell. So it's important that human eyes look at these items when determining if they're still relevant, and getting detail on an item by item basis is very easy to do. And once an admin-only user has determined none of the media is in use, they can mark them all for deletion and move them into the recycle bin. If they're really content all is well then there's even a purge button to clear the recycle bin and remove the items from disk! We have a few features that we want to add in the future: Field auditing - do you have your alt text or captions filled out? We'd like to make this "plug and play" so you can add any fields that you want and the tool will check if they're empty. Integrating the above with Umbraco AI - if a field is empty, fill it in with Umbraco AI's integrations to read media files and write alt text. Display a thumbnail of the item in the dashboard (if it's an image) to help with visual recognition Check if images don't have crops selected or set Are there any features that you'd love to see? Let us know!

by Proworks

Quick Tip: Extending the Delivery API's Content Response
A quick look at how to extend Umbraco 17’s Delivery API response with content from elsewhere in the content tree, without building a custom endpoint....

by Johan Reitsma

Notify a Teams channel when you publish content, using Umbraco Automate
Use Umbraco Automate to post a notification to a Microsoft Teams channel whenever content is published, with no custom C#. A step by step walkthrough on Umbraco 17.

by Nathaniel Nunes

Why I choose Umbraco over WordPress

Umbraco and WordPress solve different problems, and after years of building on both I know which one I want to still be maintaining in five years.

by Justin Neville

Upgrading Umbraco 13 to 17: What We Learned
What we learned upgrading a large production website from Umbraco 13 to 17, covering migrations, APIs, AngularJS, property editors, Forms, content and deployment.

by David Whalley

Umbraco on DDEV: .NET, SQL Server, and the generic project type
An experiment in running Umbraco CMS and .NET 10 under DDEV, using the generic project type, a custom web image, and Azure SQL Edge.

by Lee Mills

Building a Cloudflare Integration for Umbraco Automate
When I first started experimenting with Umbraco Automate, I wanted to find a real-world use case instead of creating an integration just for the sake of trying the API. It didn't take long to find one. On several Umbraco projects, we use Cloudflare in front of the website. When content changes, there are situations where we want to invalidate the cached version of the affected page. Traditionally, I would solve this in code: Content published ↓ Notification handler ↓ Determine published URLs ↓ Call Cloudflare API ↓ Purge cache That works. But after looking at Automate, I started wondering: What if the application doesn't need to know anything about Cloudflare at all? Instead, publishing content could simply trigger an automation, with small reusable actions taking care of the individual steps. That idea eventually resulted in three NuGet packages: Umbraco.Community.Automate Umbraco.Community.Automate.Extensions Umbraco.Community.Automate.Cloudflare All currently available as version 17.0.0 for Umbraco 17. This post describes how I got there, some of the problems I encountered, and what I learned about extending Umbraco Automate along the way. Starting with the obvious solution My first idea was simple. Umbraco Automate already provides a Content Published trigger, so I wanted to create a Cloudflare action that could take the published page and purge it from Cloudflare. Something like: Content Published ↓ Purge Cloudflare The Cloudflare API itself makes this fairly straightforward.To purge specific URLs you can send a request to: POST /client/v4/zones/{zoneId}/purge_cache with: { "files": [ "https://www.example.com/some-page/" ] } So initially I thought the Cloudflare action could simply accept the URL of the published page. The Content Published trigger doesn't provide a URL. It exposes information such as: contentKey contentName contentTypeKey contentTypeAlias cultures And actually, that makes sense. A URL isn't necessarily a property of the publish event. A content item doesn't necessarily have one URL This became the first interesting part of the implementation. Consider a multilingual Umbraco website: https://www.example.com/ https://www.example.com/en/ Now add multiple hostnames, which is perfectly valid in an Umbraco installation: https://www.example-a.com/ https://www.example-a.com/en/ https://www.example-b.com/ https://www.example-b.com/en/ For a single content item, asking: What is the URL? is therefore not always the right question. The better question is: What are the published URLs for this content item and culture? That distinction ended up having quite a large influence on the package design. Separating Umbraco from Cloudflare My first instinct was to put the URL resolution inside the Cloudflare action. The action could receive: Content Key Culture and internally: Resolve the Umbraco content. Determine its URLs. Call Cloudflare. Purge those URLs. But that didn't feel right. Resolving published URLs has nothing to do with Cloudflare. The same functionality could be useful when: notifying an external API; updating a search index; sending a webhook; invalidating another CDN; generating a sitemap; or building another Automate workflow. So instead I created a generic action: Get Published Content URLs and moved it into a separate package: Umbraco.Community.Automate.Extensions Cloudflare became its own integration: Umbraco.Community.Automate.Cloudflare This allows Automate to do what it is good at: composing small pieces of functionality. The workflow becomes: Content Published ↓ For Each Culture ↓ Get Published Content URLs ↓ Purge Cloudflare URLs That separation is probably the design decision I'm happiest with. Building Get Published Content URLs The generic action receives a content key and culture. Its settings are roughly: public sealed class GetPublishedContentUrlsSettings { public Guid ContentKey { get; set; } public string Culture { get; set; } = string.Empty; } The output deliberately contains an array: public sealed class GetPublishedContentUrlsOutput { public Guid ContentKey { get; set; } public string Culture { get; set; } = string.Empty; public string[] Urls { get; set; } = []; } Notice that it's Urls, not Url. This is important for installations where a culture is available through multiple domains. Conceptually the action does: Content Key + Culture ↓ Umbraco published content ↓ Primary + alternative URLs ↓ string[] That output can then be consumed by any other Automate action. Lesson learned: be careful with service lifetimes While building the action I ran into another useful lesson. My first implementation injected IPublishedContentQuery directly into the action. That resulted in: Cannot consume scoped service 'Umbraco.Cms.Core.IPublishedContentQuery' from singleton 'GetPublishedContentUrlsAction'. Automate actions are registered as singletons, while several Umbraco services used for published content are scoped. Injecting one directly into a singleton therefore isn't safe. Instead, the action needs to work with the appropriate Umbraco context/service scope when resolving published content. It's an easy mistake to make when building your first Automate extension because the action itself looks very similar to a normal service. The important takeaway: Always consider the lifetime of the services you inject into an Automate action. Cultures introduced another interesting problem The Content Published trigger exposes cultures. Not culture. That means a single publish operation can involve multiple cultures. The obvious workflow is therefore: Content Published ↓ For Each ↓ Get Published Content URLs The collection for the loop is: ${ trigger.cultures } And inside the loop the current culture is: ${ loop.item } Initially I accidentally passed: ${ trigger.cultures } directly into the action's Culture field. That resulted in something like: ["es"] being passed as the culture instead of: es and consequently: Content '<guid>' is not published for culture '["es"]'. The correct pattern is: For Each: ${ trigger.cultures } Get Published Content URLs: Content Key: ${ trigger.contentKey } Culture: ${ loop.item } A small mistake, but a good example of why understanding the difference between a collection binding and the current loop item matters. Then I wanted to purge multiple URLs at once Initially the Cloudflare package had: Purge Cloudflare URL with: public string Url { get; set; } = string.Empty; This worked perfectly when combined with another For Each: Get Published Content URLs ↓ For Each URL ↓ Purge Cloudflare URL But Cloudflare already accepts multiple URLs in one request. So why make one HTTP request per URL? I changed the action to: Purge Cloudflare URLs and the Cloudflare client now accepts a collection: Task PurgeUrlsAsync( string apiToken, string zoneId, IEnumerable<string> urls, CancellationToken cancellationToken = default); The resulting request can contain all URLs: { "files": [ "https://www.example-a.com/en/", "https://www.example-b.com/en/" ] } This makes the workflow much nicer: Get Published Content URLs ↓ Purge Cloudflare URLs At least, that was the idea. And then I learned something interesting about Automate bindings. Binding an array isn't the same as binding a string My first settings model looked perfectly reasonable: public sealed class PurgeUrlsSettings { public string[] Urls { get; set; } = []; } The previous action already returned: string[] Urls so I expected this binding to work: ${ previous.urls } Instead Automate failed before the action was even executed: Failed to resolve model 'community.cloudflare.purgeUrls' to type PurgeUrlsSettings. The JSON value could not be converted to System.String[]. That was confusing at first because the source value really was a string[]. The important detail is how action settings are stored. The binding itself is initially represented as: { "urls": "${ previous.urls }" } That's a string expression. If the property is already declared as string[], JSON deserialization needs to happen before that expression can resolve to its collection value. So: "${ previous.urls }" ↓ Deserialize as string[] ↓ 💥 Looking at For Each provided the answer The interesting thing was that this already worked: Get Published Content URLs ↓ For Each Collection: ${ previous.urls } So Automate clearly could consume my array. That led me into the Automate source code. The built-in For Each doesn't define its collection setting as an array. Instead, conceptually it does this: public string Collection { get; set; } = string.Empty; The setting contains the binding expression, not the resolved collection. The expression is evaluated later at runtime. That same approach works nicely for the Cloudflare action. The setting can remain: public sealed class PurgeUrlsSettings { public string Urls { get; set; } = string.Empty; } and the configured value remains: ${ previous.urls } At runtime, Automate's BindingEvaluator can evaluate the raw expression: var value = _bindingEvaluator.EvaluateRaw( settings.Urls, context.BindingData ?? new Dictionary<string, object?>()); The action can then turn that resolved value into the collection it needs. This was probably the most interesting technical lesson from building the package. Sometimes the type of a configuration property shouldn't represent the type of the eventual runtime value. In this case: Setting string expression ↓ BindingEvaluator ↓ runtime collection ↓ Cloudflare API is a better model. Normalizing the URLs Before sending anything to Cloudflare, the action normalizes the collection: urls = urls .Where(url => !string.IsNullOrWhiteSpace(url)) .Select(url => url.Trim()) .Distinct(StringComparer.OrdinalIgnoreCase) .ToArray(); Then it verifies that something remains: if (urls.Length == 0) { return ActionResult.Failed( new ArgumentException( "At least one URL is required.")); } and validates the URLs: var invalidUrl = Array.Find( urls, url => !Uri.TryCreate( url, UriKind.Absolute, out _)); if (invalidUrl is not null) { return ActionResult.Failed( new ArgumentException( $"'{invalidUrl}' is not a valid absolute URL.")); } Only after that does the action call Cloudflare. Creating a reusable Cloudflare connection I didn't want API tokens and zone IDs to be configured on every action. Automate has a connection concept for exactly this purpose, so the Cloudflare package provides its own connection type. The connection contains information such as: Account ID Zone ID API Token The API token can also be validated against Cloudflare. Cloudflare provides an endpoint for checking whether a token is valid and active, which makes the connection test much more useful than simply checking whether a value was entered. A successful response looks roughly like: { "result": { "status": "active" }, "success": true } This gives users feedback while configuring the connection instead of waiting for their first automation run to fail. Keep API tokens scoped For the Cloudflare API token, I recommend granting only the permissions required by the workflow. For cache purging, don't use a token with unnecessary account-wide permissions. The connection should know: API Token Zone ID and the action should only perform the operation it was designed for. It's a small detail, but integrations like these make security boundaries very visible. The resulting packages The experiment eventually became three packages. Umbraco.Community.Automate The convenience package. Installing it brings in the complete collection: dotnet add package Umbraco.Community.Automate Umbraco.Community.Automate.Extensions Generic Automate building blocks: dotnet add package Umbraco.Community.Automate.Extensions Currently including: Get Published Content URLs Umbraco.Community.Automate.Cloudflare The Cloudflare integration: dotnet add package Umbraco.Community.Automate.Cloudflare Currently providing the Cloudflare connection and cache purge functionality. The packages are versioned alongside their supported Umbraco major version, so the first stable release is: 17.0.0 for Umbraco 17. Why I like this approach The part I like most isn't actually the Cloudflare API integration. Calling an HTTP API isn't particularly complicated. The interesting part is the separation of responsibilities. Instead of writing: public class ContentPublishedHandler { // Find content // Determine cultures // Determine domains // Resolve URLs // Read Cloudflare configuration // Call Cloudflare // Handle failures } we can create reusable building blocks: Content Published ↓ For Each Culture ↓ Get Published Content URLs ↓ Purge Cloudflare URLs And tomorrow somebody could build: Content Published ↓ Get Published Content URLs ↓ Notify external service or: Content Published ↓ Get Published Content URLs ↓ Update search index without changing Get Published Content URLs. That's where I think Automate becomes really interesting. What I learned A few things stood out while building these packages. Actions should do one thing Get Published Content URLs shouldn't know Cloudflare exists. And Purge Cloudflare URLs shouldn't need to know anything about Umbraco content. The workflow connects them. Model collections explicitly A published content item can have multiple cultures, and one culture can have multiple URLs. Designing around collections from the start avoids assumptions that only work for simple websites. Bindings are runtime values A binding expression such as: ${ previous.urls } is stored as a string but may resolve to something completely different at runtime. Looking at how Automate's own For Each implementation handles this was extremely useful. Watch your DI lifetimes Automate actions and Umbraco scoped services don't necessarily share the same lifetime. Be careful when injecting services such as published-content APIs directly into actions. Composition beats coupling The Cloudflare use case resulted in a generic action that turned out to be useful completely independently of Cloudflare. That's a good sign that the responsibility belongs in its own extension. What's next? There are plenty of directions this could go. Cloudflare supports more than purging individual URLs, so possible future actions include: Purge by cache tag Purge by prefix Purge by hostname Purge everything But I don't want one giant "Cloudflare action" with every possible option. I'd rather keep each operation explicit and let Automate compose them. The generic Extensions package also opens the door to other reusable Umbraco actions that aren't tied to a specific integration. And that's probably what I find most interesting about Automate: once you start thinking in small triggers, actions and outputs, you quickly start seeing automation opportunities everywhere. Try it The packages are available on NuGet: Umbraco.Community.Automate Umbraco.Community.Automate.Extensions Umbraco.Community.Automate.Cloudflare Source code, examples and issues are available on GitHub: https://github.com/erikjanwestendorp/Umbraco.Community.Automate The project is open source, so feedback, ideas, issues and pull requests are very welcome. If you're experimenting with Umbraco Automate as well, I'd love to hear what kind of integrations or reusable actions you're building.

by Erik-Jan Westendorp

Building my own Umbraco Lamp

I have wanted an UmbLamp ever since Matt Brailsford posted it back in November 2023, but I did not own a 3D printer. That finally changed this July, so I ordered the parts and built one. Here is what I used, what went wrong, and the one mistake worth avoiding before you start.

by Justin Neville

From Examine to Umbraco Search

Demonstrating an approach to migrate a site from Examine to Umbraco Search

by Kenn Jacobsen